
量化
警告
量化处于测试阶段,可能会发生变化。
量化简介 ¶
量化是指执行计算和存储张量时使用低于浮点精度位宽的技术。量化模型在执行张量操作时使用的是降低精度的值,而不是全精度(浮点)值。这允许模型表示更加紧凑,并在许多硬件平台上使用高性能的矢量化操作。与典型的 FP32 模型相比,PyTorch 支持 INT8 量化,可以实现模型大小和内存带宽需求减少 4 倍。INT8 计算的硬件支持通常比 FP32 计算快 2 到 4 倍。量化主要是为了加速推理,仅支持量化算子的正向传递。
PyTorch 支持多种深度学习模型的量化方法。在大多数情况下,模型是在 FP32 精度下训练的,然后将其转换为 INT8 精度。此外,PyTorch 还支持量化感知训练,该训练在正向和反向传播过程中使用伪量化模块来模拟量化误差。请注意,整个计算都是在浮点数下进行的。在量化感知训练结束时,PyTorch 提供了转换函数,可以将训练好的模型转换为低精度。
在较低级别,PyTorch 提供了一种表示量化张量并对其执行操作的方法。它们可以直接构建在低精度下执行所有或部分计算的模型。还提供了高级 API,这些 API 结合了将 FP32 模型转换为低精度的工作流程,以最小化精度损失。
量化 API 摘要
PyTorch 提供了三种不同的量化模式:急切模式量化、FX 图模式量化(维护中)和 PyTorch 2 导出量化。
热切模式量化是一个测试功能。用户需要手动进行融合并指定量化和反量化的位置,而且它只支持模块,不支持函数。
FX 图模式量化是 PyTorch 中的自动化量化工作流程,目前它是一个原型功能,由于我们有 PyTorch 2 导出量化,它处于维护模式。它通过添加对函数的支持并自动化量化过程来改进热切模式量化,尽管人们可能需要重构模型以使模型与 FX 图模式量化兼容(可以通过 torch.fx 符号化跟踪)。请注意,FX 图模式量化可能无法在任意模型上工作,因为模型可能无法进行符号化跟踪,我们将将其集成到领域库如 torchvision 中,用户可以使用 FX 图模式量化量化与支持领域库中类似的模型。对于任意模型,我们将提供一般性指南,但为了使其真正工作,用户可能需要熟悉 torch.fx ,特别是如何使模型符号化跟踪。
PyTorch 2 导出量化是新的全图模式量化工作流程,作为原型功能在 PyTorch 2.1 中发布。随着 PyTorch 2 的推出,我们正在转向更好的全程序捕获(torch.export)解决方案,因为它可以捕获更高比例(14K 模型上的 88.8%)的模型,相比于 FX 图模式量化使用的 torch.fx.symbolic_trace(14K 模型上的 72.7%),torch.export 在一些 Python 构造上仍有限制,需要用户参与以支持导出模型中的动态性,但总体上它比之前的程序捕获解决方案有所改进。PyTorch 2 导出量化是为由 torch.export 捕获的模型构建的,考虑到建模用户和后端开发者的灵活性和生产力。主要特性包括(1)可编程 API,用于配置模型如何量化,可以扩展到更多用例(2)简化了建模用户和后端开发者的用户体验,因为他们只需要与单个对象(量化器)交互,以表达用户对如何量化模型以及后端支持的意图。(3) 可选的参考量化模型表示,可以表示使用整数运算的量化计算,更接近硬件中实际发生的量化计算。
建议量化新用户首先尝试 PyTorch 2 导出量化,如果效果不佳,用户可以尝试急切模式量化。
下表比较了急切模式量化、FX 图模式量化与 PyTorch 2 导出量化的区别:
急切模式量化 |
沉浸式翻译模式量化 |
PyTorch 2 导出量化 |
|
发布状态 |
测试版 |
原型(维护中) |
原型 |
运算符融合 |
手动 |
自动 |
自动 |
量化/反量化定位 |
手动 |
自动 |
自动 |
模块量化 |
支持 |
支持 |
支持 |
量化泛函/PyTorch 操作 |
手动 |
自动 |
支持 |
支持定制 |
有限支持 |
完全支持 |
全面支持 |
量化模式支持 |
基于训练的量化:静态、动态、仅权重 量化感知训练:静态 |
训练后量化:静态、动态、权重仅 量化感知训练:静态 |
由后端特定量化器定义 |
输入/输出模型类型 |
|
|
|
支持三种量化类型:
动态量化(权重量化,激活值以浮点数读取/存储,并在计算时量化)
静态量化(权重量化,激活量化,训练后需要校准)
静态量化感知训练(权重量化,激活量化,在训练期间对量化数值建模)
请参阅我们关于 PyTorch 量化介绍的博客文章,以获取这些量化类型之间权衡的更全面概述。
动态和静态量化之间的算子覆盖范围不同,如下表所示。
静态量化 |
动态量化 |
|
nn.Linear
nn.Conv1d/2d/3d
|
Y
Y
|
Y
N
|
nn.LSTM
nn.GRU
|
Y(通过)
自定义模块)
N
|
Y
Y
|
nn.RNNCell
nn.GRUCell
nn.LSTMCell
|
N
N
N
|
Y
Y
Y
|
nn.EmbeddingBag |
Y (激活值以 fp32 格式存储) |
Y |
nn.Embedding |
Y |
Y |
nn.MultiheadAttention |
Y(通过自定义模块) |
不支持 |
激活函数 |
广泛支持 |
未改变,计算保持为 fp32 |
贪婪模式量化 ¶
想要了解量化流程的通用介绍,包括不同类型的量化,请参阅通用量化流程。
训练后动态量化 ¶
这是最简单的量化形式,权重在训练前量化,但在推理过程中动态量化激活。这种情况适用于模型执行时间主要由从内存中加载权重而不是计算矩阵乘法所主导的情况。这对于小批量大小的 LSTM 和 Transformer 类型模型来说是真的。
图表:
# original model
# all tensors and computations are in floating point
previous_layer_fp32 -- linear_fp32 -- activation_fp32 -- next_layer_fp32
                 /
linear_weight_fp32

# dynamically quantized model
# linear and LSTM weights are in int8
previous_layer_fp32 -- linear_int8_w_fp32_inp -- activation_fp32 -- next_layer_fp32
                     /
   linear_weight_int8
PTDQ API 示例:
import torch

# define a floating point model
class M(torch.nn.Module):
    def __init__(self):
        super().__init__()
        self.fc = torch.nn.Linear(4, 4)

    def forward(self, x):
        x = self.fc(x)
        return x

# create a model instance
model_fp32 = M()
# create a quantized model instance
model_int8 = torch.ao.quantization.quantize_dynamic(
    model_fp32,  # the original model
    {torch.nn.Linear},  # a set of layers to dynamically quantize
    dtype=torch.qint8)  # the target dtype for quantized weights

# run the model
input_fp32 = torch.randn(4, 4, 4, 4)
res = model_int8(input_fp32)
要了解更多关于动态量化的信息,请参阅我们的动态量化教程。
后训练静态量化 ¶
后训练静态量化(PTQ 静态)量化模型的权重和激活。尽可能地将激活融合到前面的层中。它需要与代表性数据集进行校准,以确定激活的最佳量化参数。后训练静态量化通常在内存带宽和计算节省都很重要时使用,卷积神经网络(CNN)是一个典型用例。
在应用后训练静态量化之前,我们可能需要修改模型。请参阅“Eager Mode 静态量化模型准备”。
图:
# original model
# all tensors and computations are in floating point
previous_layer_fp32 -- linear_fp32 -- activation_fp32 -- next_layer_fp32
                    /
    linear_weight_fp32

# statically quantized model
# weights and activations are in int8
previous_layer_int8 -- linear_with_activation_int8 -- next_layer_int8
                    /
  linear_weight_int8
PTSQ API 示例:
import torch

# define a floating point model where some layers could be statically quantized
class M(torch.nn.Module):
    def __init__(self):
        super().__init__()
        # QuantStub converts tensors from floating point to quantized
        self.quant = torch.ao.quantization.QuantStub()
        self.conv = torch.nn.Conv2d(1, 1, 1)
        self.relu = torch.nn.ReLU()
        # DeQuantStub converts tensors from quantized to floating point
        self.dequant = torch.ao.quantization.DeQuantStub()

    def forward(self, x):
        # manually specify where tensors will be converted from floating
        # point to quantized in the quantized model
        x = self.quant(x)
        x = self.conv(x)
        x = self.relu(x)
        # manually specify where tensors will be converted from quantized
        # to floating point in the quantized model
        x = self.dequant(x)
        return x

# create a model instance
model_fp32 = M()

# model must be set to eval mode for static quantization logic to work
model_fp32.eval()

# attach a global qconfig, which contains information about what kind
# of observers to attach. Use 'x86' for server inference and 'qnnpack'
# for mobile inference. Other quantization configurations such as selecting
# symmetric or asymmetric quantization and MinMax or L2Norm calibration techniques
# can be specified here.
# Note: the old 'fbgemm' is still available but 'x86' is the recommended default
# for server inference.
# model_fp32.qconfig = torch.ao.quantization.get_default_qconfig('fbgemm')
model_fp32.qconfig = torch.ao.quantization.get_default_qconfig('x86')

# Fuse the activations to preceding layers, where applicable.
# This needs to be done manually depending on the model architecture.
# Common fusions include `conv + relu` and `conv + batchnorm + relu`
model_fp32_fused = torch.ao.quantization.fuse_modules(model_fp32, [['conv', 'relu']])

# Prepare the model for static quantization. This inserts observers in
# the model that will observe activation tensors during calibration.
model_fp32_prepared = torch.ao.quantization.prepare(model_fp32_fused)

# calibrate the prepared model to determine quantization parameters for activations
# in a real world setting, the calibration would be done with a representative dataset
input_fp32 = torch.randn(4, 1, 4, 4)
model_fp32_prepared(input_fp32)

# Convert the observed model to a quantized model. This does several things:
# quantizes the weights, computes and stores the scale and bias value to be
# used with each activation tensor, and replaces key operators with quantized
# implementations.
model_int8 = torch.ao.quantization.convert(model_fp32_prepared)

# run the model, relevant calculations will happen in int8
res = model_int8(input_fp32)
了解静态量化,请参阅静态量化教程。
量化感知训练用于静态量化
量化感知训练(QAT)在训练过程中模拟量化效果,与其它量化方法相比,可以实现更高的精度。我们可以对静态、动态或仅权重量化进行 QAT。在训练过程中,所有计算都使用浮点数进行,通过 fake_quant 模块通过钳位和舍入来模拟 INT8 的效果。在模型转换后,权重和激活量进行量化,并在可能的情况下将激活量融合到前一层。它通常与 CNN 一起使用,与静态量化相比,精度更高。
在应用训练后静态量化之前,我们可能需要修改模型。请参阅“Eager Mode 静态量化模型准备”。
图表:
# original model
# all tensors and computations are in floating point
previous_layer_fp32 -- linear_fp32 -- activation_fp32 -- next_layer_fp32
                      /
    linear_weight_fp32

# model with fake_quants for modeling quantization numerics during training
previous_layer_fp32 -- fq -- linear_fp32 -- activation_fp32 -- fq -- next_layer_fp32
                           /
   linear_weight_fp32 -- fq

# quantized model
# weights and activations are in int8
previous_layer_int8 -- linear_with_activation_int8 -- next_layer_int8
                     /
   linear_weight_int8
QAT API 示例:
import torch

# define a floating point model where some layers could benefit from QAT
class M(torch.nn.Module):
    def __init__(self):
        super().__init__()
        # QuantStub converts tensors from floating point to quantized
        self.quant = torch.ao.quantization.QuantStub()
        self.conv = torch.nn.Conv2d(1, 1, 1)
        self.bn = torch.nn.BatchNorm2d(1)
        self.relu = torch.nn.ReLU()
        # DeQuantStub converts tensors from quantized to floating point
        self.dequant = torch.ao.quantization.DeQuantStub()

    def forward(self, x):
        x = self.quant(x)
        x = self.conv(x)
        x = self.bn(x)
        x = self.relu(x)
        x = self.dequant(x)
        return x

# create a model instance
model_fp32 = M()

# model must be set to eval for fusion to work
model_fp32.eval()

# attach a global qconfig, which contains information about what kind
# of observers to attach. Use 'x86' for server inference and 'qnnpack'
# for mobile inference. Other quantization configurations such as selecting
# symmetric or asymmetric quantization and MinMax or L2Norm calibration techniques
# can be specified here.
# Note: the old 'fbgemm' is still available but 'x86' is the recommended default
# for server inference.
# model_fp32.qconfig = torch.ao.quantization.get_default_qconfig('fbgemm')
model_fp32.qconfig = torch.ao.quantization.get_default_qat_qconfig('x86')

# fuse the activations to preceding layers, where applicable
# this needs to be done manually depending on the model architecture
model_fp32_fused = torch.ao.quantization.fuse_modules(model_fp32,
    [['conv', 'bn', 'relu']])

# Prepare the model for QAT. This inserts observers and fake_quants in
# the model needs to be set to train for QAT logic to work
# the model that will observe weight and activation tensors during calibration.
model_fp32_prepared = torch.ao.quantization.prepare_qat(model_fp32_fused.train())

# run the training loop (not shown)
training_loop(model_fp32_prepared)

# Convert the observed model to a quantized model. This does several things:
# quantizes the weights, computes and stores the scale and bias value to be
# used with each activation tensor, fuses modules where appropriate,
# and replaces key operators with quantized implementations.
model_fp32_prepared.eval()
model_int8 = torch.ao.quantization.convert(model_fp32_prepared)

# run the model, relevant calculations will happen in int8
res = model_int8(input_fp32)
想了解更多关于量化感知训练的信息,请参阅 QAT 教程。
想要为急切模式静态量化准备模型
在进行急切模式量化之前,需要对模型定义进行一些修改。这是因为当前的量化是按模块进行的。具体来说,对于所有量化技术,用户需要:
将需要输出再量化的任何操作(因此具有额外的参数)从函数形式转换为模块形式(例如,使用
torch.nn.ReLU代替torch.nn.functional.relu)。指定模型中需要量化的部分,可以通过在子模块上分配
.qconfig属性或通过指定qconfig_mapping来实现。例如,设置model.conv1.qconfig = None表示model.conv层将不会量化,设置model.linear1.qconfig = custom_qconfig表示model.linear1的量化设置将使用custom_qconfig而不是全局 qconfig。
对于量化激活的静态量化技术,用户还需要做以下操作:
指定激活的量化和去量化位置。这通过使用
QuantStub和DeQuantStub模块来完成。使用
FloatFunctional将需要特殊量化处理的张量操作封装到模块中。例如,像add和cat这样的操作需要特殊处理来确定输出量化参数。融合模块:将操作/模块组合成一个单一模块以获得更高的准确性和性能。这通过使用
fuse_modules()API 完成,该 API 接受要融合的模块列表。我们目前支持以下融合:[Conv, Relu],[Conv, BatchNorm],[Conv, BatchNorm, Relu],[Linear, Relu]
(原型 - 维护模式)FX 图模式量化
在训练后量化中存在多种量化类型(仅权重、动态和静态),配置通过 qconfig_mapping(prepare_fx 函数的参数)完成。
FXPTQ API 示例:
import torch
from torch.ao.quantization import (
  get_default_qconfig_mapping,
  get_default_qat_qconfig_mapping,
  QConfigMapping,
)
import torch.ao.quantization.quantize_fx as quantize_fx
import copy

model_fp = UserModel()

#
# post training dynamic/weight_only quantization
#

# we need to deepcopy if we still want to keep model_fp unchanged after quantization since quantization apis change the input model
model_to_quantize = copy.deepcopy(model_fp)
model_to_quantize.eval()
qconfig_mapping = QConfigMapping().set_global(torch.ao.quantization.default_dynamic_qconfig)
# a tuple of one or more example inputs are needed to trace the model
example_inputs = (input_fp32)
# prepare
model_prepared = quantize_fx.prepare_fx(model_to_quantize, qconfig_mapping, example_inputs)
# no calibration needed when we only have dynamic/weight_only quantization
# quantize
model_quantized = quantize_fx.convert_fx(model_prepared)

#
# post training static quantization
#

model_to_quantize = copy.deepcopy(model_fp)
qconfig_mapping = get_default_qconfig_mapping("qnnpack")
model_to_quantize.eval()
# prepare
model_prepared = quantize_fx.prepare_fx(model_to_quantize, qconfig_mapping, example_inputs)
# calibrate (not shown)
# quantize
model_quantized = quantize_fx.convert_fx(model_prepared)

#
# quantization aware training for static quantization
#

model_to_quantize = copy.deepcopy(model_fp)
qconfig_mapping = get_default_qat_qconfig_mapping("qnnpack")
model_to_quantize.train()
# prepare
model_prepared = quantize_fx.prepare_qat_fx(model_to_quantize, qconfig_mapping, example_inputs)
# training loop (not shown)
# quantize
model_quantized = quantize_fx.convert_fx(model_prepared)

#
# fusion
#
model_to_quantize = copy.deepcopy(model_fp)
model_fused = quantize_fx.fuse_fx(model_to_quantize)
请按照以下教程了解 FX Graph 模式量化:
(原型) PyTorch 2 导出量化 ¶
API 示例:
import torch
from torch.ao.quantization.quantize_pt2e import prepare_pt2e
from torch.export import export_for_training
from torch.ao.quantization.quantizer import (
    XNNPACKQuantizer,
    get_symmetric_quantization_config,
)

class M(torch.nn.Module):
    def __init__(self):
        super().__init__()
        self.linear = torch.nn.Linear(5, 10)

   def forward(self, x):
       return self.linear(x)

# initialize a floating point model
float_model = M().eval()

# define calibration function
def calibrate(model, data_loader):
    model.eval()
    with torch.no_grad():
        for image, target in data_loader:
            model(image)

# Step 1. program capture
# NOTE: this API will be updated to torch.export API in the future, but the captured
# result should mostly stay the same
m = export_for_training(m, *example_inputs).module()
# we get a model with aten ops

# Step 2. quantization
# backend developer will write their own Quantizer and expose methods to allow
# users to express how they
# want the model to be quantized
quantizer = XNNPACKQuantizer().set_global(get_symmetric_quantization_config())
# or prepare_qat_pt2e for Quantization Aware Training
m = prepare_pt2e(m, quantizer)

# run calibration
# calibrate(m, sample_inference_data)
m = convert_pt2e(m)

# Step 3. lowering
# lower to target backend
请按照以下教程开始使用 PyTorch 2 导出量化:
模型用户:
后端开发者(请查看所有建模用户文档):
量化栈 ¶
量化是将浮点模型转换为量化模型的过程。因此,从高层次来看,量化栈可以分为两个部分:1)量化模型的构建块或抽象 2)将浮点模型转换为量化模型的量化流程的构建块或抽象
量化模型 ¶
量化张量 ¶
为了在 PyTorch 中进行量化,我们需要能够以张量的形式表示量化数据。量化张量允许存储量化数据(以 int8/uint8/int32 表示)以及量化参数,如缩放和零点。量化张量允许进行许多有用的操作,使得量化算术变得简单,同时还允许以量化格式序列化数据。
PyTorch 支持张量级和通道级的对称与非对称量化。张量级表示张量内的所有值以相同的方式使用相同的量化参数进行量化。通道级表示对于每个维度,通常是张量的通道维度,张量内的值使用不同的量化参数进行量化。这允许在将张量转换为量化值时减少误差,因为异常值只会影响其所在的通道,而不是整个张量。
通过将浮点张量转换为执行映射
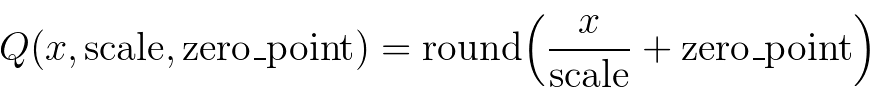
注意,我们确保在量化后浮点数中的零不会产生错误,从而确保填充等操作不会引起额外的量化误差。
下面是量化张量的一些关键属性:
QScheme(torch.qscheme):一个枚举,用于指定量化张量的方式
torch.per_tensor_affine
torch.per_tensor_symmetric
torch.per_channel_affine
torch.per_channel_symmetric
dtype (torch.dtype):量化张量的数据类型
torch.quint8
torch.qint8
torch.qint32
torch.float16
量化参数(根据 QScheme 变化):所选量化方式的参数
torch.per_tensor_affine 将具有量化参数
缩放(浮点数)
零点(整数)
torch.per_channel_affine 将具有量化参数
每通道尺度(浮点数列表)
每通道零点(整数列表)
轴(整数)
量化与反量化
模型的输入和输出是浮点张量,但量化模型的激活是经过量化的,因此我们需要操作符来在浮点张量和量化张量之间进行转换。
量化(浮点 -> 量化)
torch.quantize_per_tensor(x, scale, zero_point, dtype)
torch.quantize_per_channel(x, scales, zero_points, axis, dtype)
torch.quantize_per_tensor_dynamic(x, dtype, reduce_range)
to(torch.float16)
Dequantize (量化 -> 浮点数)
quantized_tensor.dequantize() - 调用 dequantize 对 torch.float16 Tensor 进行转换,将 Tensor 转回 torch.float
torch.dequantize(x)
量化算子/模块
量化算子是接受量化 Tensor 作为输入,并输出量化 Tensor 的算子。
量化模块是执行量化操作的 PyTorch 模块。它们通常用于定义加权操作,如线性操作和卷积操作。
量化引擎
当量化模型执行时,qengine(torch.backends.quantized.engine)指定了用于执行的底层后端。确保 qengine 与量化模型在量化激活和权重的值域方面兼容是很重要的。
量化流程
观察器和 FakeQuantize
Observer 是 PyTorch 模块,用于:
收集张量统计信息,如张量通过观察器的最小值和最大值
并根据收集到的张量统计信息计算量化参数
FakeQuantize 是 PyTorch 模块,用于:
模拟量化(执行量化/反量化)网络中的张量
它可以根据从观察器收集的统计数据计算量化参数,也可以学习量化参数
QConfig¶
QConfig 是一个由 Observer 或 FakeQuantize 模块类组成的 namedtuple,可以配置 qscheme、dtype 等参数,用于配置操作符应该如何被观察
操作符/模块的量化配置
不同的 Observer/FakeQuantize 类型
数据类型
q 方案
quant_min/quant_max:可用于模拟低精度张量
目前支持激活和权重配置
根据为给定操作符或模块配置的 qconfig,插入输入/权重/输出观察者
沉浸式量化流程
通常情况下,流程如下
准备
根据用户指定的 qconfig 插入 Observer/FakeQuantize 模块
校准/训练(根据后训练量化或量化感知训练)
允许观察者收集统计信息或 FakeQuantize 模块学习量化参数
转换
将校准/训练后的模型转换为量化模型
量化有不同的模式,可以分为两种:
就量化流程的应用位置而言,我们有:
训练后量化(在训练后应用量化,量化参数基于样本校准数据计算)
量化感知训练(在训练过程中模拟量化,以便量化参数可以与模型一起使用训练数据学习)
关于如何量化算子,我们可以有:
权重仅量化(只有权重是静态量化的)
动态量化(权重是静态量化的,激活是动态量化的)
静态量化(权重和激活都是静态量化的)
我们可以在同一个量化流程中混合不同的算子量化方式。例如,我们可以有既包含静态量化又包含动态量化的训练后量化。
量化支持矩阵 ¶
量化模式支持 ¶
量化模式 |
数据集要求 |
最适用场景 |
准确度 |
笔记 |
||
训练后量化 |
动态/权重量化 |
动态量化(fp16,int8)或未量化,权重静态量化(fp16,int8,in4) |
无 |
LSTM,MLP,嵌入,Transformer |
好 |
使用简单,当性能受计算或内存限制时,接近静态量化 |
静态量化 |
激活和权重静态量化(int8) |
校准数据集 |
CNN |
良好 |
提供最佳性能,可能对准确性有较大影响,适用于仅支持 int8 计算的硬件 |
|
量化感知训练 |
动态量化 |
激活和权重进行了假量化 |
微调数据集 |
多层感知器,嵌入 |
最好 |
目前仅限部分支持 |
静态量化 |
激活和权重进行了假量化 |
微调数据集 |
卷积神经网络、多层感知器、嵌入 |
最佳 |
通常在静态量化导致精度不佳时使用,用于缩小精度差距 |
|
请参阅我们关于 PyTorch 量化介绍的博客文章,以获得这些量化类型之间权衡的更全面概述。
量化流程支持
PyTorch 提供了两种量化模式:急切模式量化(Eager Mode Quantization)和 FX 图模式量化(FX Graph Mode Quantization)。
急切模式量化是一个测试版功能。用户需要手动进行融合并指定量化和去量化发生的位置,而且它只支持模块,不支持函数式。
FX Graph 模式量化是 PyTorch 中的一个自动化量化框架,目前它还是一个原型功能。它通过添加对函数的支持并自动化量化过程来改进 Eager 模式量化,尽管人们可能需要重构模型以使模型兼容 FX Graph 模式量化(可以通过 torch.fx 进行符号追踪)。请注意,FX Graph 模式量化可能无法在任意模型上工作,因为模型可能无法进行符号追踪。我们将将其集成到领域库如 torchvision 中,用户可以使用 FX Graph 模式量化对类似支持的领域库中的模型进行量化。对于任意模型,我们将提供一般性指南,但为了使其真正工作,用户可能需要熟悉 torch.fx ,特别是如何使模型可符号追踪。
建议量化新用户首先尝试 FX Graph 模式量化,如果不起作用,用户可以尝试遵循使用 FX Graph 模式量化的指南或回退到急切模式量化。
以下表格比较了急切模式量化与 FX 图模式量化的区别:
急切模式量化 |
FX 图模式量化 |
|
发布状态 |
测试版 |
原型 |
运算符融合 |
手动 |
自动 |
量化/反量化定位 |
手动 |
自动 |
量化模块 |
支持 |
支持 |
函数量化/Torch 操作 |
手册 |
自动 |
支持定制 |
有限支持 |
完全支持 |
量化模式支持 |
训练后量化:静态、动态、权重仅 量化感知训练:静态 |
训练后量化:静态、动态、权重仅 量化感知训练:静态 |
输入/输出模型类型 |
|
(可能需要一些重构以使模型兼容 FX 图模式量化) |
后端/硬件支持
硬件 |
内核库 |
渴望模式量化 |
FX 图模式量化 |
量化模式支持 |
服务器 CPU |
fbgemm/onednn |
支持 |
所有支持 |
|
移动 CPU |
qnnpack/xnnpack |
|||
服务器 GPU |
TensorRT(早期原型) |
不支持此功能,需要图 |
支持 |
静态量化 |
今天,PyTorch 支持以下后端以高效运行量化算子:
支持 AVX2 或更高版本的 x86 CPU(没有 AVX2 的一些操作实现效率较低),通过 fbgemm 和 onednn 优化 x86(详细信息请参阅 RFC)
ARM CPU(通常在移动/嵌入式设备中找到),通过 qnnpack
(早期原型)通过 TensorRT 通过 fx2trt 支持 NVidia GPU(即将开源)
原生 CPU 后端笔记
我们使用相同的原生 PyTorch 量化算子公开 x86 和 qnnpack,因此需要额外的标志来区分它们。根据 PyTorch 构建模式自动选择 x86 和 qnnpack 的对应实现,尽管用户可以通过设置 torch.backends.quantization.engine 为 x86 或 qnnpack 来覆盖此设置。
在准备量化模型时,必须确保 qconfig 和用于量化计算的引擎与模型将要执行的底层相匹配。qconfig 控制量化过程中使用的观察者的类型。qengine 控制在为线性、卷积函数和模块打包权重时是否使用 x86 或 qnnpack 特定的打包函数。例如:
x86 的默认设置:
# set the qconfig for PTQ
# Note: the old 'fbgemm' is still available but 'x86' is the recommended default on x86 CPUs
qconfig = torch.ao.quantization.get_default_qconfig('x86')
# or, set the qconfig for QAT
qconfig = torch.ao.quantization.get_default_qat_qconfig('x86')
# set the qengine to control weight packing
torch.backends.quantized.engine = 'x86'
qnnpack 的默认设置:
# set the qconfig for PTQ
qconfig = torch.ao.quantization.get_default_qconfig('qnnpack')
# or, set the qconfig for QAT
qconfig = torch.ao.quantization.get_default_qat_qconfig('qnnpack')
# set the qengine to control weight packing
torch.backends.quantized.engine = 'qnnpack'
操作符支持 §
操作符覆盖范围在动态和静态量化之间有所不同,并在下表中体现。注意,对于 FX 图模式量化,相应的功能也得到支持。
静态量化 |
动态量化 |
|
nn.Linear
nn.Conv1d/2d/3d
|
Y
Y
|
Y
N
|
nn.LSTM
nn.GRU
|
N
N
|
Y
Y
|
nn.RNNCell
nn.GRUCell
nn.LSTMCell
|
N
N
N
|
Y
Y
Y
|
nn.EmbeddingBag |
Y (激活为 fp32) |
Y |
nn.Embedding |
Y |
Y |
nn.MultiheadAttention |
不支持 |
不支持 |
激活 |
广泛支持 |
未更改,计算保持为 fp32 |
注意:这将被很快更新为从 native backend_config_dict 生成的某些信息。
量化 API 参考 ¶
量化 API 参考文档包含了量化 API 的文档,例如量化算子、量化张量操作以及支持的量化模块和函数。
量化后端配置 ¶
量化后端配置文档包含了如何配置各种后端的量化工作流的文档。
量化精度调试 ¶
量化精度调试文档包含了如何调试量化精度的文档。
量化自定义
虽然提供了基于观察到的张量数据的默认实现来选择缩放因子和偏差的观察者,但开发者可以提供自己的量化函数。量化可以针对模型的各个部分进行选择性应用,或针对模型的各个部分进行不同的配置。
我们还提供了对 conv1d()、conv2d()、conv3d()和 linear()的通道量化支持。
量化工作流程通过在模型的模块层次结构中添加(例如,添加观察者作为 .observer 子模块)或替换(例如,将 nn.Conv2d 转换为 nn.quantized.Conv2d )子模块来实现。这意味着在整个过程中,模型保持为常规的 nn.Module -based 实例,因此可以与 PyTorch API 的其他部分一起工作。
量化自定义模块 API ¶
Eager 模式与 FX 图模式量化 API 都为用户提供了一个钩子,允许用户以自定义方式指定模块的量化,并使用用户定义的逻辑进行观察和量化。用户需要指定:
源 fp32 模块的 Python 类型(存在于模型中)
观察模块的 Python 类型(由用户提供)。此模块需要定义一个 from_float 函数,用于定义如何从原始 fp32 模块创建观察模块。
量化模块的 Python 类型(由用户提供)。此模块需要定义一个 from_observed 函数,用于定义如何从观察模块创建量化模块。
描述上述(1)、(2)、(3)的配置,传递给量化 API。
框架随后将执行以下操作:
在准备模块交换过程中,它将(1)中指定的每个模块类型转换为(2)中指定的类型,使用(2)类中的 from_float 函数。
在转换模块交换过程中,它将(2)中指定的每个模块类型转换为(3)中指定的类型,使用(3)类中的 from_observed 函数。
目前,要求 ObservedCustomModule 只有一个 Tensor 输出,并且框架(而不是用户)将在这个输出上添加观察者。观察者将作为自定义模块实例的属性存储在 activation_post_process 键下。放松这些限制可能在未来进行。
自定义 API 示例:
import torch
import torch.ao.nn.quantized as nnq
from torch.ao.quantization import QConfigMapping
import torch.ao.quantization.quantize_fx

# original fp32 module to replace
class CustomModule(torch.nn.Module):
    def __init__(self):
        super().__init__()
        self.linear = torch.nn.Linear(3, 3)

    def forward(self, x):
        return self.linear(x)

# custom observed module, provided by user
class ObservedCustomModule(torch.nn.Module):
    def __init__(self, linear):
        super().__init__()
        self.linear = linear

    def forward(self, x):
        return self.linear(x)

    @classmethod
    def from_float(cls, float_module):
        assert hasattr(float_module, 'qconfig')
        observed = cls(float_module.linear)
        observed.qconfig = float_module.qconfig
        return observed

# custom quantized module, provided by user
class StaticQuantCustomModule(torch.nn.Module):
    def __init__(self, linear):
        super().__init__()
        self.linear = linear

    def forward(self, x):
        return self.linear(x)

    @classmethod
    def from_observed(cls, observed_module):
        assert hasattr(observed_module, 'qconfig')
        assert hasattr(observed_module, 'activation_post_process')
        observed_module.linear.activation_post_process = \
            observed_module.activation_post_process
        quantized = cls(nnq.Linear.from_float(observed_module.linear))
        return quantized

#
# example API call (Eager mode quantization)
#

m = torch.nn.Sequential(CustomModule()).eval()
prepare_custom_config_dict = {
    "float_to_observed_custom_module_class": {
        CustomModule: ObservedCustomModule
    }
}
convert_custom_config_dict = {
    "observed_to_quantized_custom_module_class": {
        ObservedCustomModule: StaticQuantCustomModule
    }
}
m.qconfig = torch.ao.quantization.default_qconfig
mp = torch.ao.quantization.prepare(
    m, prepare_custom_config_dict=prepare_custom_config_dict)
# calibration (not shown)
mq = torch.ao.quantization.convert(
    mp, convert_custom_config_dict=convert_custom_config_dict)
#
# example API call (FX graph mode quantization)
#
m = torch.nn.Sequential(CustomModule()).eval()
qconfig_mapping = QConfigMapping().set_global(torch.ao.quantization.default_qconfig)
prepare_custom_config_dict = {
    "float_to_observed_custom_module_class": {
        "static": {
            CustomModule: ObservedCustomModule,
        }
    }
}
convert_custom_config_dict = {
    "observed_to_quantized_custom_module_class": {
        "static": {
            ObservedCustomModule: StaticQuantCustomModule,
        }
    }
}
mp = torch.ao.quantization.quantize_fx.prepare_fx(
    m, qconfig_mapping, torch.randn(3,3), prepare_custom_config=prepare_custom_config_dict)
# calibration (not shown)
mq = torch.ao.quantization.quantize_fx.convert_fx(
    mp, convert_custom_config=convert_custom_config_dict)
最佳实践 ¶
1. 如果您使用的是 x86 后端,我们需要使用 7 位而不是 8 位。请确保您减少 quant\_min 、 quant\_max 的范围,例如,如果 dtype 是 torch.quint8 ,请确保设置自定义的 quant_min 为 0 , quant_max 为 127 ( 255 / 2 )。如果 dtype 是 torch.qint8 ,请确保设置自定义的 quant_min 为 -64 ( -128 / 2 ), quant_max 为 63 ( 127 / 2 ),如果您调用 torch.ao.quantization.get_default_qconfig(backend)或 torch.ao.quantization.get_default_qat_qconfig(backend)函数来获取 qconfig 后端或 x86 后端的默认 qnnpack ,我们已经正确设置了这些。
如果选择 onednn 后端,默认 qconfig 映射 torch.ao.quantization.get_default_qconfig_mapping('onednn') 和默认 qconfig torch.ao.quantization.get_default_qconfig('onednn') 将使用 8 位激活。建议在支持向量神经网络指令(VNNI)的 CPU 上使用。否则,将激活的观察者的 reduce_range 设置为 True,以在无 VNNI 支持的 CPU 上获得更好的精度。
常见问题
我如何在 GPU 上执行量化推理?
目前我们还没有官方的 GPU 支持,但这是一个活跃的开发领域,您可以在此处找到更多信息。
我在哪里可以获得 ONNX 对量化模型的支持?
如果你在导出模型时遇到错误(使用
torch.onnx下的 API),你可以在 PyTorch 仓库中提交一个问题。在问题标题前加上[ONNX],并将问题标记为module: onnx。如果你在 ONNX Runtime 中遇到问题,请在 GitHub - microsoft/onnxruntime 上提交一个问题。
我该如何使用 LSTM 的量化?
LSTM 支持通过我们的自定义模块 API 在 eager mode 和 fx graph mode 量化。示例可以在 Eager Mode: pytorch/test_quantized_op.py TestQuantizedOps.test_custom_module_lstm FX Graph Mode: pytorch/test_quantize_fx.py TestQuantizeFx.test_static_lstm 找到
常见错误 ¶
将未量化的 Tensor 传递给量化内核 ¶
如果您看到类似以下错误:
RuntimeError: Could not run 'quantized::some_operator' with arguments from the 'CPU' backend...
这意味着您正在尝试将一个未量化的 Tensor 传递给一个量化的内核。一个常见的解决方案是使用 torch.ao.quantization.QuantStub 来量化 Tensor。在 Eager 模式量化中,这需要手动完成。一个端到端示例:
class M(torch.nn.Module):
    def __init__(self):
        super().__init__()
        self.quant = torch.ao.quantization.QuantStub()
        self.conv = torch.nn.Conv2d(1, 1, 1)

    def forward(self, x):
        # during the convert step, this will be replaced with a
        # `quantize_per_tensor` call
        x = self.quant(x)
        x = self.conv(x)
        return x
将量化的 Tensor 传递给非量化的内核
如果您看到类似以下错误:
RuntimeError: Could not run 'aten::thnn_conv2d_forward' with arguments from the 'QuantizedCPU' backend.
这意味着您正在尝试将量化的 Tensor 传递给非量化的内核。一个常见的解决方案是使用 torch.ao.quantization.DeQuantStub 来反量化 Tensor。在 Eager 模式量化中,这需要手动完成。一个端到端示例:
class M(torch.nn.Module):
    def __init__(self):
        super().__init__()
        self.quant = torch.ao.quantization.QuantStub()
        self.conv1 = torch.nn.Conv2d(1, 1, 1)
        # this module will not be quantized (see `qconfig = None` logic below)
        self.conv2 = torch.nn.Conv2d(1, 1, 1)
        self.dequant = torch.ao.quantization.DeQuantStub()

    def forward(self, x):
        # during the convert step, this will be replaced with a
        # `quantize_per_tensor` call
        x = self.quant(x)
        x = self.conv1(x)
        # during the convert step, this will be replaced with a
        # `dequantize` call
        x = self.dequant(x)
        x = self.conv2(x)
        return x

m = M()
m.qconfig = some_qconfig
# turn off quantization for conv2
m.conv2.qconfig = None
保存和加载量化模型
当在量化模型上调用 torch.load 时,如果您看到如下错误:
AttributeError: 'LinearPackedParams' object has no attribute '_modules'
这是因为直接使用 torch.save 和 torch.load 保存和加载量化模型是不支持的。要保存/加载量化模型,可以使用以下方法:
保存/加载量化模型的状态字典
例子:
class M(torch.nn.Module):
    def __init__(self):
        super().__init__()
        self.linear = nn.Linear(5, 5)
        self.relu = nn.ReLU()

    def forward(self, x):
        x = self.linear(x)
        x = self.relu(x)
        return x

m = M().eval()
prepare_orig = prepare_fx(m, {'' : default_qconfig})
prepare_orig(torch.rand(5, 5))
quantized_orig = convert_fx(prepare_orig)

# Save/load using state_dict
b = io.BytesIO()
torch.save(quantized_orig.state_dict(), b)

m2 = M().eval()
prepared = prepare_fx(m2, {'' : default_qconfig})
quantized = convert_fx(prepared)
b.seek(0)
quantized.load_state_dict(torch.load(b))
使用
torch.jit.save和torch.jit.load保存/加载脚本化量化模型
例子:
# Note: using the same model M from previous example
m = M().eval()
prepare_orig = prepare_fx(m, {'' : default_qconfig})
prepare_orig(torch.rand(5, 5))
quantized_orig = convert_fx(prepare_orig)

# save/load using scripted model
scripted = torch.jit.script(quantized_orig)
b = io.BytesIO()
torch.jit.save(scripted, b)
b.seek(0)
scripted_quantized = torch.jit.load(b)
使用 FX 图模式量化时出现的符号跟踪错误
符号跟踪是(原型 - 维护模式)FX 图模式量化的要求,因此如果您传递一个无法通过 torch.ao.quantization.prepare_fx 或 torch.ao.quantization.prepare_qat_fx 进行符号跟踪的 PyTorch 模型,我们可能会看到以下错误:
torch.fx.proxy.TraceError: symbolically traced variables cannot be used as inputs to control flow
请参阅符号跟踪的限制和使用 FX 图模式量化的用户指南,以解决此问题。
